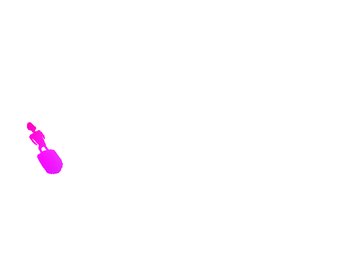Images, text, camera, depth and flow share one token interface, so a task is just a choice of what to give and what to predict. There are endlessly many; here is a selection. Click one, or build your own prompt.
Give
→
Predict
2 Adaptivity
Adaptive streams of thought
Ψ-0.6 chooses the representations it reasons through. For each question it decides which streams to think with (depth, motion, camera, an imagined scene), generates them itself, and answers with them in context. Reinforcement learning on task feedback teaches it which streams help.
One checkpoint plays three roles: it writes a notation naming the streams it wants, generates each of them from the video, then answers. Each video pauses at every stream Ψ-0.6 chose and fades in its prediction.
AgiBot World · robot“What is the robot doing with the toast?” → Putting it into the toaster ✓ · video alone: wrongRoboVQA · mobile robot“Where will the robot put the box?” → On the table ✓Ego4D · EgoPlan-Bench2“Goal: prepare for washing. What is the next action?” → Drop spoon in sink ✓Ego4D · EgoPlan-Bench2“Goal: prepare ingredients. What is the next action?” → Put cooking pan on cooker ✓
+5.6%
relative accuracy over video-only answering, held-out data
+9.0%
on four unseen benchmarks
Relative accuracy gain over answering from the video alone
random notations
Ψ-0.6 policy
Held-out data from the training sources
EgoDex+12.5%EgoDexvideo only 47.5% · random notations 50.2% · Ψ-0.6 policy 53.5%
SSv2+6.4%SSv2video only 82.3% · random notations 86.2% · Ψ-0.6 policy 87.5%
OpenVid+1.9%OpenVidvideo only 92.2% · random notations 94.7% · Ψ-0.6 policy 94.0%
PE+1.5%PEvideo only 84.2% · random notations 84.0% · Ψ-0.6 policy 85.4%
Unseen benchmarks
HanDyVQA+10.0%HanDyVQAvideo only 23.9% · random notations 25.6% · Ψ-0.6 policy 26.3%
STAR+11.5%STARvideo only 29.4% · random notations 30.5% · Ψ-0.6 policy 32.8%
EgoPlan-Bench2+10.1%EgoPlan-Bench2video only 25.9% · random notations 26.8% · Ψ-0.6 policy 28.6%
TGIF-QA+4.0%TGIF-QAvideo only 31.4% · random notations 31.9% · Ψ-0.6 policy 32.6%
0+5%+10%
Show as table
Benchmark
Set
Video only
Random
Policy
Random gain
Policy gain
EgoDex
Held-out
47.5
50.2
53.5
+5.5%
+12.5%
SSv2
Held-out
82.3
86.2
87.5
+4.8%
+6.4%
OpenVid
Held-out
92.2
94.7
94.0
+2.7%
+1.9%
PE
Held-out
84.2
84.0
85.4
-0.2%
+1.5%
HanDyVQA
Unseen
23.9
25.6
26.3
+7.1%
+10.0%
STAR
Unseen
29.4
30.5
32.8
+3.6%
+11.5%
EgoPlan-Bench2
Unseen
25.9
26.8
28.6
+3.4%
+10.1%
TGIF-QA
Unseen
31.4
31.9
32.6
+1.8%
+4.0%
Multiple-choice accuracy (%), one sampled notation per question. Gains are relative to the same model answering from the video alone.
Benchmark numbers use precomputed streams scored by a frozen copy of the model; the examples above run the whole loop in one checkpoint. Examples are selected.
On MindCube, Ψ-0.6 estimates how each view is rotated, picks the view the question asks about, and answers from it.
MindCube · rotation · zero-shot
Q “If I am standing at the same spot and facing the same direction as shown in image 1, what is to my right?” Options: A. green cabinet · B. window and brown cabinet · C. several pictures
Inputviews
image 1image 2image 3
Ψ-0.6
Visionestimate camera motion
c1→2 · yaw -95°c1→3 · yaw -145°
Reasoningpick the view
image 2 · closest to a 90° right turn
Languageanswer
B. window and brown cabinet
Ground truth: B. window and brown cabinet
49.7%
MindCube, answering directly (zero-shot)
57.7%
thinking in camera motion first
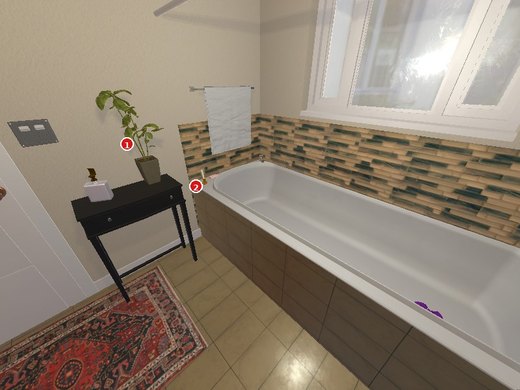
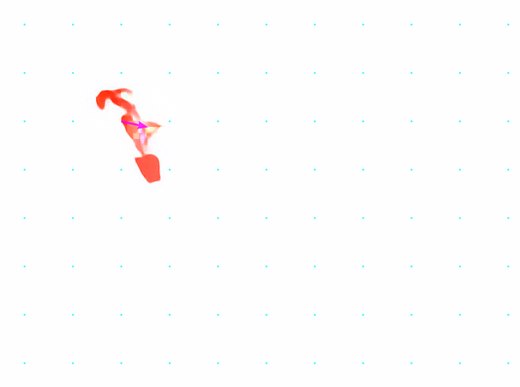
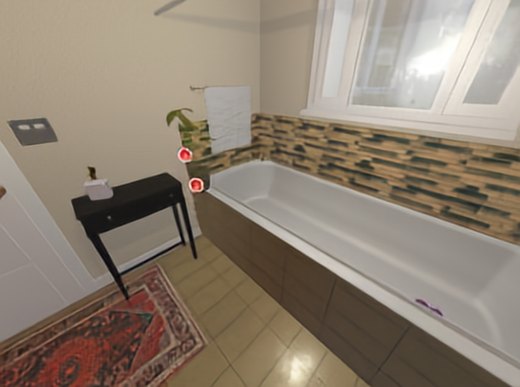
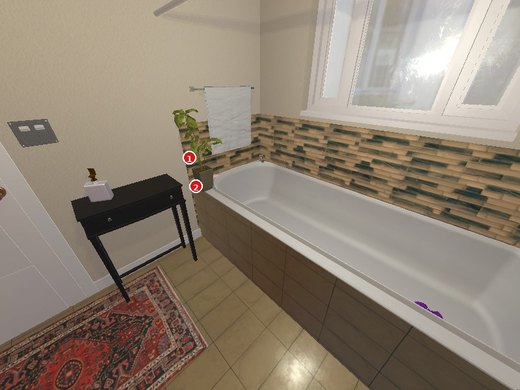
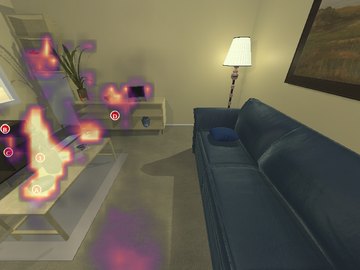
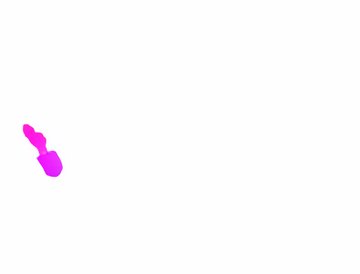
Asked about a move that never happened, Ψ-0.6 turns the command into optical flow, renders the scene after the move, and reasons over its own imagined frame (FlowBench).
FlowBench-Sim · Occlusion
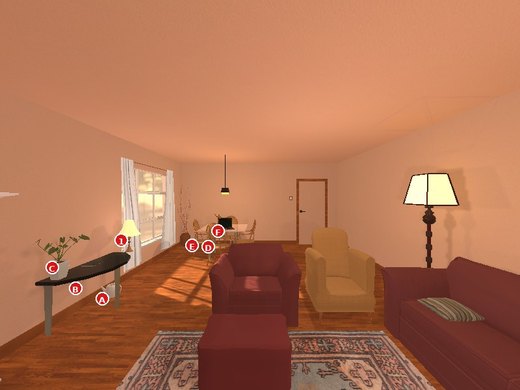
“Move the houseplant (1) 0.39m right and 0.12m down.” In the after image, is the candle (2) occluded by the object (1) so that a part of it is invisible, or is it totally visible? Options: A. totally visible (not occluded). · B. a part is invisible (occluded).
Inputscene + command
rgb0 · marked objects
Ψ-0.6
World modelingimagine the move
f0→1 · imagined motion
rgb1 · imagined view
Languagereasoning trace
The houseplant has been shifted slightly to the right and a bit downward, moving closer to the sidetable. In the after image, the plant now overlaps with the area where the candle sits. The leaves extend over the candle, covering a noticeable portion of it. While part of the candle remains visible, a significant section is hidden behind the plant’s foliage. The occlusion is clear and substantial, not just a minor overlap. The candle is no longer fully visible due to the plant’s new position.
Languageanswer
B. a part is invisible (occluded).
Ground truth: B. a part is invisible (occluded).
what actually happened (simulator)
FlowBench-Sim · Count nearby
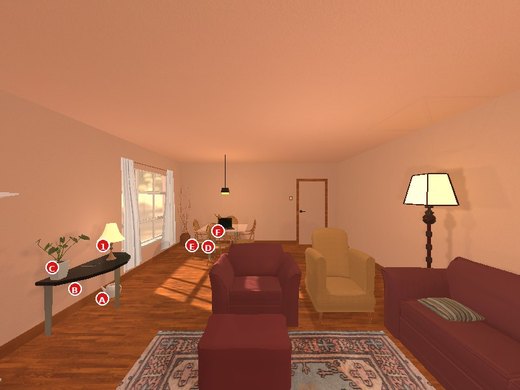
“Move the desklamp (1) 0.40m along the camera forward axis.” After the move, how many of the following objects are within 1.00m of the desklamp (1)? Objects: (A) the wateringcan; (B) the sidetable; (C) the houseplant; (D) the chair; (E) the chair; (F) the laptop. Options: A. 5 · B. 2 · C. 3 · D. 4
Inputscene + command
rgb0 · marked objects
Ψ-0.6
World modelingimagine the move
f0→1 · imagined motion
rgb1 · imagined view
Languagereasoning trace
The desklamp is currently on the small round table near the left wall, close to the houseplant and the first chair from the left. Moving it forward a short distance along the camera’s view pushes it slightly away from the table but keeps it in the same general area. The houseplant remains right beside it, still very close. The first chair from the left is also nearby, just a bit to the left and slightly behind the lamp’s new position. The sidetable is farther away, across the room, and the laptop is on the red sofa, which is also at a noticeable distance. The second chair from the left is even farther, near the back wall. After the move, only the houseplant and the first chair stay within arm’s reach of the lamp.
Languageanswer
B. 2
Ground truth: B. 2
what actually happened (simulator)
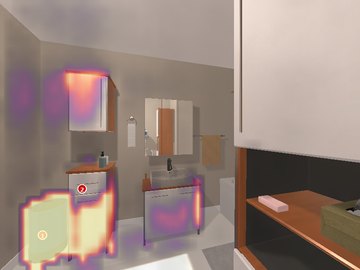
FlowBench-Sim · Left or right
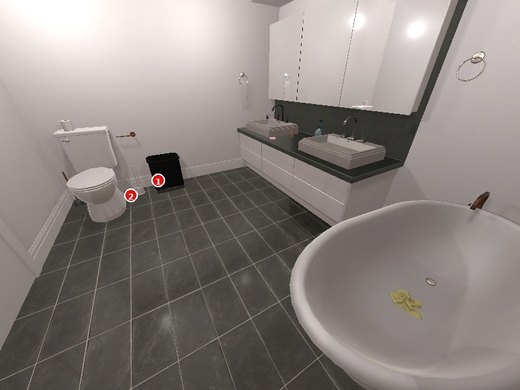
“Move the garbagecan (1) 0.50m left.” In the after image, is the garbagecan (1) to the left of the scrubbrush (2) from the camera's viewpoint? Options: A. no — from the camera, the stated side relation is false. · B. yes — from the camera, the stated side relation is true.
Inputscene + command
rgb0 · marked objects
Ψ-0.6
World modelingimagine the move
f0→1 · imagined motion
rgb1 · imagined view
Languagereasoning trace
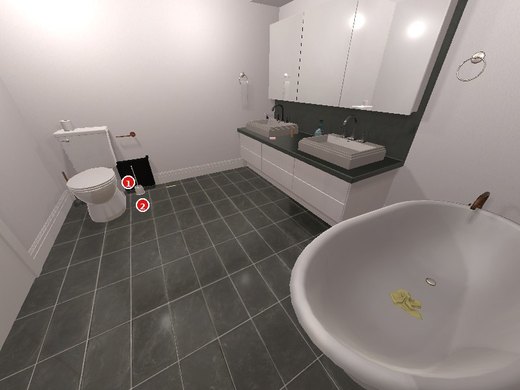
The garbagecan was moved slightly to the left, closer to the toilet. In the after image, the garbagecan sits near the left wall, just beside the toilet. The scrubbrush is visible on the sink, which is further to the right in the scene. From the camera’s viewpoint, the garbagecan is clearly positioned to the left of the scrubbrush. The relative positions haven’t changed in a way that would shift the garbagecan to the right. The scrubbrush remains on the right side of the frame, while the garbagecan is now more centered but still left of the scrubbrush.
Languageanswer
B. yes — from the camera, the stated side relation is true.
Ground truth: B. yes — from the camera, the stated side relation is true.
what actually happened (simulator)
How Ψ-0.6 imagines a commanded move
One forward pass estimates which patches are likely to move; flow is then decoded most-likely-first, with classifier-free guidance on the command.
commandprobability of motionpredicted flowground truth
tGQ0 · command“Move the house plant (1) 0.60m along the camera forward axis”
p(motion) · where it moves
f0→1 · Ψ-0.6
f0→1 · simulator
tGQ0 · command“Move the statue (1) 1.05m along the camera forward axis”
p(motion) · where it moves
f0→1 · Ψ-0.6
f0→1 · simulator
tGQ0 · command“Move the garbagecan (1) 0.90m right”
p(motion) · where it moves
f0→1 · Ψ-0.6
f0→1 · simulator
tGQ0 · command“Move the desklamp (1) 0.40m right”
p(motion) · where it moves
f0→1 · Ψ-0.6
f0→1 · simulator
56.4%
text-to-flow accuracy (modular experts 50.8%)
57.5%
sim-to-real transfer on FlowBench-Real
Citation
BibTeX
@article{psi06_2026,
  title   = {$\Psi$-0.6: Adaptive Streams of Thought in a Unified Vision-Language
             World Model},
  author  = {Aw, Khai Loong and Kotar, Klemen and Zhang, Baihan and Liu, Yifan and
             Chen, Lilian and Kazemian, Atlas and Venkatesh, Rahul and Yamins, Daniel},
  journal = {arXiv preprint arXiv:2610.32177},
  year    = {2026}
}
 Ψ-0.6